Imputation Overview
| Pipeline Version | Date Updated | Documentation Author | Questions or Feedback |
|---|---|---|---|
| See changelog for version information. | See changelog | Terra Scientific Pipeline Services | Please file an issue in WARP. |
Introduction to the Array Imputation pipeline
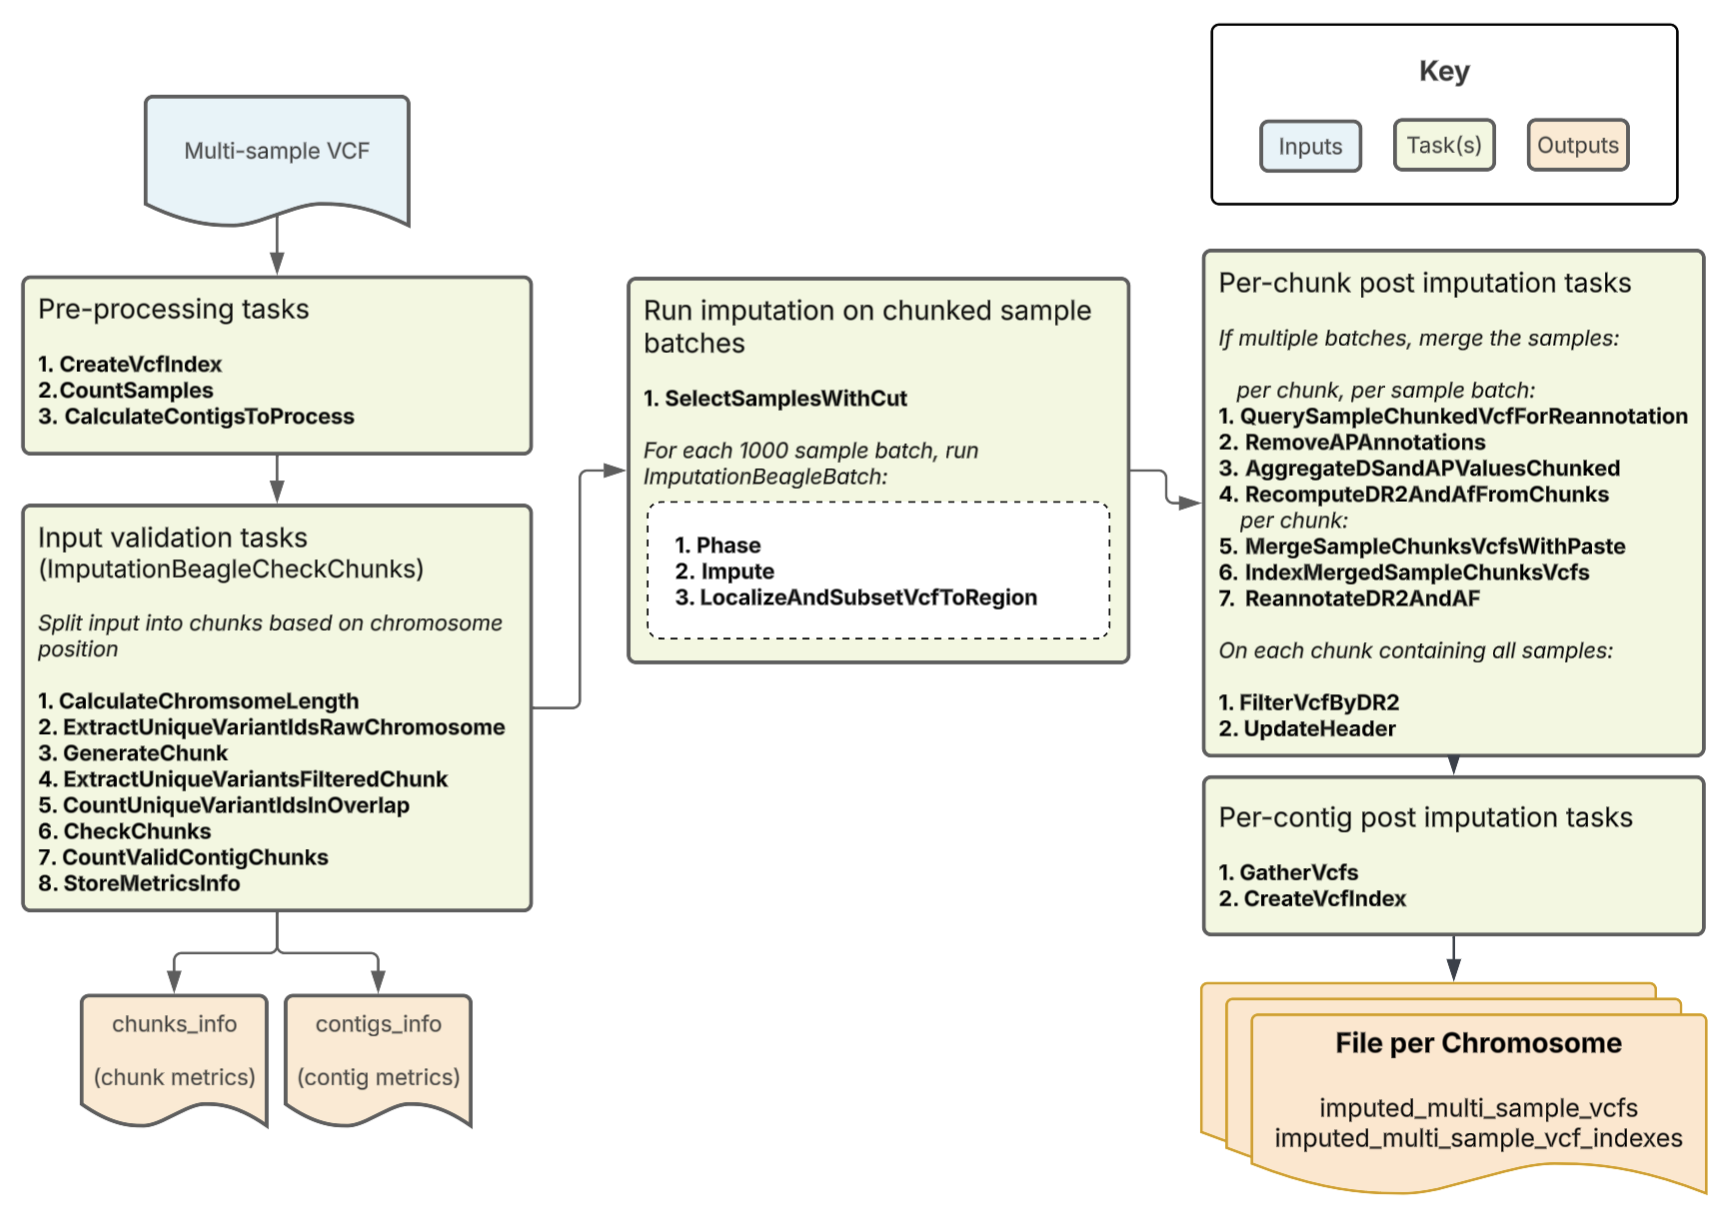
The Array Imputation pipeline imputes missing genotypes from a multi-sample VCF using a large genomic reference panel. It uses Beagle for phasing and imputation. The workflow chunks each requested contig by position, validates each chunk against the reference panel, splits the chunks into sample batches, phases/imputes each sample batch, strips overlap regions, merges the sample batches back together, and emits per-contig imputed VCFs with QC summaries.
The pipeline is composed of two sub-workflows orchestrated by ImputationBeagle.wdl:
ImputationBeagleCheckChunkssplits the input VCF into position chunks (with overlaps) for each contig and validates every chunk against the reference panel.ImputationBeagleBatchphases and imputes one sample batch (designed to scale to approximately 1000 samples) across all pre-made chunks. It runs once per sample batch.
Because the input is chunked by position once and then split by sample (rather than the reverse), the position-chunk and reference-panel checks run a single time regardless of the number of samples. The version of each sub-workflow is tracked in its own changelog (CheckChunks, Batch).
Set-up
Workflow installation and requirements
The Array Imputation workflow is written in the Workflow Description Language (WDL) and can be deployed using a WDL-compatible execution engine like Cromwell, a GA4GH-compliant workflow manager that supports multiple computing platforms.
To identify the latest workflow version and release notes, see the Imputation workflow changelog.
Using the Array Imputation pipeline
This pipeline is used by the All of Us + AnVIL Imputation Service. If you choose to use this service, you can impute your samples against the reference panel hosted in cloud storage.
You can alternatively run the pipeline with your own panel, using this WDL.
Input descriptions
The table below describes the Array Imputation pipeline inputs. The workflow requires a multi-sample VCF and a reference-panel layout for the contigs being processed.
For examples of how to specify each input in a configuration file, see the example input JSONs.
| Input name | Description | Type |
|---|---|---|
multi_sample_vcf | Multi-sample VCF file containing genotype data. | File |
ref_dict | Reference dictionary used to calculate contig lengths and update VCF headers. | File |
contigs | Allowed contigs/chromosomes to process. The workflow filters the input VCF to these contigs. | Array[String] |
reference_panel_path_prefix | Prefix to the reference panel files for all contigs (e.g. .../panel.<chr>). | String |
genetic_maps_path | Prefix to the genetic map files for all contigs. | String |
output_basename | Basename used for intermediate and final outputs. | String |
chunk_length | Size of each genomic chunk in base pairs; default 25000000. | Int |
chunk_overlaps | Padding added to each chunk to reduce edge effects; default 2000000. | Int |
sample_chunk_size | Number of samples processed per imputation sample batch; the input is split into ceil(n_samples / sample_chunk_size) batches after position chunking. Default 1000. | Int |
pipeline_header_line | Optional additional VCF header line to append to output VCFs. | String? |
min_dr2_for_inclusion | Minimum DR2 threshold to include a variant in the final output VCF; default 0.0 (disabled). | Float? |
bref3_suffix | Suffix used for reference panel .bref3 files; default .bref3. | String |
unique_variant_ids_suffix | Suffix used for per-contig unique-variant ID files; default .unique_variants. | String |
gatk_docker | Docker image used by GATK-based tasks; default us.gcr.io/broad-gatk/gatk:4.6.0.0. | String |
ubuntu_docker | Docker image used for dictionary/utility tasks; default us.gcr.io/broad-dsde-methods/ubuntu:20.04. | String |
error_count_override | Optional override for QC failure count; set to 0 to continue despite failed chunks. | Int? |
beagle_cpu | Beagle CPU count for phase/impute tasks; default 8. | Int |
beagle_phase_memory_in_gb | Memory for Beagle phase step; default 40. | Int |
beagle_impute_memory_in_gb | Memory for Beagle impute step; default 45. | Int |
merge_sample_chunks_vcfs_with_paste_preemptible_sample_cutoff | Sample-count cutoff for setting preemptible = 0 on MergeSampleChunksVcfsWithPaste; default 10000. | Int |
recompute_dr2_and_af_from_chunks_preemptible_sample_cutoff | Sample-count cutoff for setting preemptible = 0 on RecomputeDR2AndAfFromChunks; default 30000. | Int |
reannotate_dr2_and_af_preemptible_sample_cutoff | Sample-count cutoff for setting preemptible = 0 on ReannotateDR2AndAF; default 4000. | Int |
Workflow tasks and tools
The Array Imputation workflow imports the ImputationBeagleCheckChunks and ImputationBeagleBatch sub-workflows, along with tasks from ImputationTasks.wdl and ImputationBeagleTasks.wdl. The table below summarizes the tasks and their roles; the Where column indicates whether a task runs in the main workflow or in one of the sub-workflows.
| Task name (alias) in WDL | Tool | Software | Description | Where |
|---|---|---|---|---|
CreateVcfIndex | index | bcftools | Indexes the input multi-sample VCF so later tasks can query and subset it efficiently. | Main |
CountSamples | query | bcftools | Counts the number of samples in the input VCF to drive sample-chunking and resource sizing. | Main |
CalculateContigsToProcess | custom script | Python / bash | Determines which contigs in the input VCF are eligible for imputation based on the workflow contigs input. | Main |
CalculateChromosomeLength | grep / bash | bash | Reads chromosome lengths from the reference dictionary and derives chunk bounds for each contig. | CheckChunks |
ExtractUniqueVariantIds | SelectVariants + query | GATK + bcftools | Extracts unique CHROM:POS:REF:ALT identifiers for a contig or chunk to compare against the reference panel. | CheckChunks |
GenerateChunk | SelectVariants | GATK | Extracts each position chunk (including overlaps) from the input VCF. | CheckChunks |
CountUniqueVariantIdsInOverlap | comm | bash | Counts the overlap between filtered chunk variants and the panel’s unique variant IDs. | CheckChunks |
CheckChunks | custom validation | bcftools / bash | Validates the chunk QC check and marks chunks with insufficient overlap or too few variants. | CheckChunks |
CountValidContigChunks | bash | bash | Counts invalid chunks so the workflow can fail early if QC is not acceptable. | CheckChunks |
FailQCNChunks (ErrorWithMessageIfErrorCountNotZero) | bash | bash | Stops the workflow if the number of failed chunks is non-zero, unless overridden. | CheckChunks |
SelectSamplesWithCut | cut | bash | Splits each position-chunked VCF into sample batches when the input has more samples than sample_chunk_size. | Main |
Phase | Beagle | Beagle | Phases the filtered chunk using the reference panel and genetic map. | Batch |
Impute | Beagle | Beagle | Performs Beagle imputation for the phased chunk. | Batch |
LocalizeAndSubsetVcfToRegion | SelectVariants | GATK | Removes the overlap padding from each imputed chunk so that only the intended genomic interval remains. | Batch |
QuerySampleChunkedVcfForReannotation | query | bcftools | Extracts the DS/AP annotations needed to recompute DR2 and AF after sample-chunk merging. | Main |
RemoveAPAnnotations | annotate | bcftools | Removes AP annotations from each sample-batch VCF before merging to reduce file size. | Main |
AggregateDSandAPValuesChunked | Python | Python | Aggregates DS/AP values for each sample-batch VCF from the query output; memory use scales inversely with sample count. | Main |
MergeSampleChunksVcfsWithPaste | Paste + view | bash + bcftools | Merges per-sample-batch VCFs back together by pasting sample columns. | Main |
IndexMergedSampleChunksVcfs | index | bcftools | Builds the VCF index for the merged sample-chunk result. | Main |
RecomputeDR2AndAfFromChunks | Python | Python | Streams the per-sample-batch DR2/AF summary files once and writes the combined annotation table incrementally. | Main |
ReannotateDR2AndAF | annotate | bcftools | Adds the merged DR2/AF values back to the sample-merged VCF. | Main |
FilterVcfByDR2 | filter | GATK | Removes variants below the min_dr2_for_inclusion threshold when a threshold is supplied. | Main |
UpdateHeader | UpdateVCFSequenceDictionary | GATK | Updates the VCF header with the reference dictionary and any optional pipeline header line. | Main |
GatherVcfsNoIndex | Combine VCFs | bcftools | Merges the per-chunk VCFs for a contig into a single contig-level VCF. | Main |
CreateIndexForGatheredVcfContig | index | bcftools | Creates the index for the final per-contig VCF. | Main |
StoreMetricsInfo | Python / pandas | Python | Aggregates chunk- and contig-level variant QC metrics into the final metrics tables. | CheckChunks |
Workflow outputs
The table below summarizes the workflow outputs. These appear as arrays of per-contig VCFs and QC metrics tables.
| Output name | Description | Type |
|---|---|---|
imputed_multi_sample_vcfs | Final imputed multi-sample VCFs, one per contig. | Array[File] |
imputed_multi_sample_vcf_indexes | Index files for the per-contig imputed VCFs. | Array[File] |
chunks_info | TSV produced by StoreMetricsInfo containing chunk-level intervals, variant counts, and pass/fail status for each chunk. | File |
contigs_info | TSV produced by StoreMetricsInfo containing contig-level summary metrics for the processed chromosomes. | File |
ArrayImputationQuotaConsumed summary
The auxiliary QuotaConsumed workflow computes the service quota metric for the Array Imputation workflow by counting the number of samples in the input multi-sample VCF.
Inputs
| Input | Description |
|---|---|
multi_sample_vcf | Input VCF from which the sample count is derived. |
output_basename | Basename kept for API compatibility with the service layer. |
min_dr2_for_inclusion | Optional DR2 filter value retained for interface consistency; not used by the quota workflow. |
contigs | Requested contigs; retained for interface compatibility. |
genetic_maps_path | Genetic-map path retained for interface compatibility. |
ref_dict | Reference dictionary retained for interface compatibility. |
reference_panel_path_prefix | Reference-panel prefix retained for interface compatibility. |
pipeline_header_line | Optional header line retained for interface compatibility. |
Outputs
| Output | Description |
|---|---|
quota_consumed | Number of samples in the input VCF (CountSamples.nSamples). |
ArrayImputationQC summary
The auxiliary InputQC workflow validates the input multi-sample VCF before the imputation job runs. It checks chromosome compatibility, VCF structure, and basic reference-panel compatibility using the shared QC task library.
Inputs
| Input | Description |
|---|---|
multi_sample_vcf | Input VCF to evaluate. |
output_basename | Basename kept for interface compatibility. |
min_dr2_for_inclusion | Optional DR2 filter retained for interface compatibility. |
contigs | Allowed contigs for the workflow. |
genetic_maps_path | Genetic maps path retained for compatibility with service interfaces. |
ref_dict | Reference dictionary used for contig and header checks. |
reference_panel_path_prefix | Reference-panel prefix retained for compatibility. |
pipeline_header_line | Optional header line retained for compatibility. |
Outputs
| Output | Description |
|---|---|
passes_qc | Boolean indicating whether the input passed the QC checks. |
qc_messages | Optional string describing any QC failure messages. |
QC checks
The QcChecks task performs the App/analysis-side validation for the input VCF, including checks such as:
- VCF format version compatibility
- contig compatibility with the expected reference assembly
- absence of obvious array/WGS data issues that would invalidate imputation
- basic structural checks for sorted/valid VCF records
- compatibility with the reference dictionary and allowed contig set
Important notes
- Runtime parameters are optimized for Broad's Google Cloud Platform implementation.
- The workflow fails early (in
ImputationBeagleCheckChunks, before any imputation) when a chunk fails the reference-panel overlap QC, unlesserror_count_overrideis set to permit continuation. - When the input has more samples than
sample_chunk_size, each position chunk is split into sample batches, imputed with allele probabilities, and merged after recomputing DR2/AF annotations. With a single batch, these merge steps are skipped.
Citing the Imputation Pipeline
If you use the Imputation Pipeline in your research, please consider citing our preprint:
Degatano, K., Awdeh, A., Cox III, R.S., Dingman, W., Grant, G., Khajouei, F., Kiernan, E., Konwar, K., Mathews, K.L., Palis, K., et al. Warp Analysis Research Pipelines: Cloud-optimized workflows for biological data processing and reproducible analysis. Bioinformatics 2025; btaf494. https://doi.org/10.1093/bioinformatics/btaf494
Contact us
Help us make our tools better by filing an issue in WARP; we welcome pipeline-related suggestions or questions.
Licensing
Copyright Broad Institute, 2020 | BSD-3
The workflow script is released under the WDL open source code license (BSD-3) (full license text at https://github.com/broadinstitute/warp/blob/master/LICENSE). However, please note that the programs it calls may be subject to different licenses. Users are responsible for checking that they are authorized to run all programs before running this script.